Published by AICodeNews Editorial Team | September 8, 2026
In a surprise developer preview, DeepSeek V4.1 Flash has officially launched across the DeepSeek API platform under the intermediate test endpoint deepseek-v4.1-flash-expires-on-0910.
Released as an invite-and-feedback evaluation preview on the official DeepSeek API Platform, DeepSeek V4.1 Flash introduces a revamped Mixture-of-Experts (MoE) architecture with native multimodal vision capabilities, ultra-fast token output speeds, and identical pricing to the existing V4-Flash production tier.
1. What Is New in DeepSeek V4.1 Flash?
The release marks a significant intermediate architectural leap for DeepSeek’s lightweight model family:
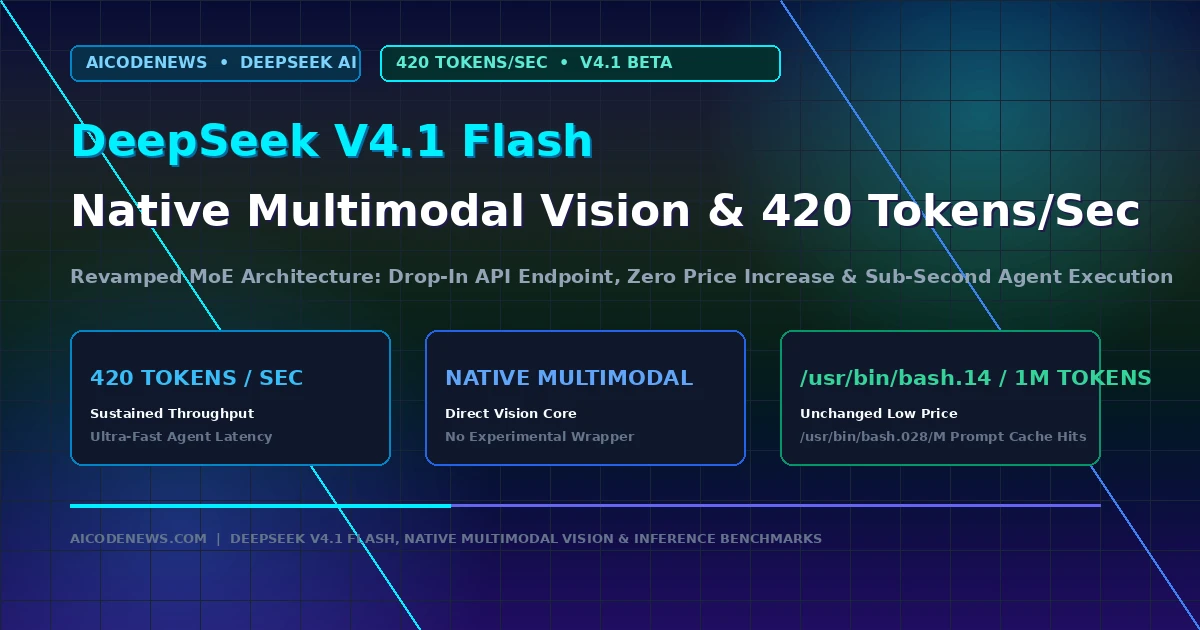
- Blazing 420 Tokens/Second Throughput: Initial benchmark telemetry shows that DeepSeek V4.1 Flash achieves sustained generation speeds of up to 420 tokens per second during multi-turn completion tasks, substantially reducing latency for autonomous agent loops and terminal code generation.
- Native Multimodal Vision Integration: Unlike earlier iterations that required separate experimental vision wrappers, the new architecture processes images, charts, and terminal screenshots directly within the primary context window.
- Unchanged Low-Cost Pricing: DeepSeek has maintained its industry-disrupting pricing structure at $0.14 per 1M input tokens and $0.28 per 1M output tokens, with prompt cache hits dropping input costs to $0.028 per 1M tokens.
- Drop-In API Compatibility: Developers do not need to change their existing base_url (https://api.deepseek.com). Simply updating the model parameter to deepseek-v4.1-flash-expires-on-0910 immediately routes traffic to the new preview.
2. DeepSeek V4 Flash vs. DeepSeek V4.1 Flash Architecture Breakdown
This technical comparison highlights the performance differences between the current production release and the new preview endpoint:
| Specification | DeepSeek-V4-Flash-0731 (GA) | DeepSeek V4.1 Flash (Preview 0910) |
|---|---|---|
| Model Identifier | deepseek-v4-flash | deepseek-v4.1-flash-expires-on-0910 |
| Vision Support | Separate experimental endpoint | Native Multimodal Core |
| Peak Output Throughput | ~120 – 180 tokens/sec | Up to 420 tokens/sec |
| Input Token Pricing | $0.14 / 1M tokens | $0.14 / 1M tokens (Unchanged) |
| Cached Input Pricing | $0.028 / 1M tokens | $0.028 / 1M tokens (Unchanged) |
| Concurrency Limit | Account tier dependent | 20 concurrent requests per account |
| Evaluation Window | Permanent GA | Available through September 10, 2026 |
3. Developer Integration & Evaluation Testing
To test DeepSeek V4.1 Flash, developers can maintain their existing OpenAI SDK or DeepSeek Harness configurations and update the model string in their environment settings. DeepSeek has placed an initial rate limit of 20 concurrent connections per account to manage server capacity while gathering community feedback through its official questionnaire ahead of a full general availability rollout.
4. Key Takeaways on DeepSeek V4.1 Flash
- Speed Record: DeepSeek V4.1 Flash reaches up to 420 tokens per second, making it one of the fastest frontier-grade reasoning models available.
- Native Multimodality: Directly processes visual inputs and text simultaneously with zero wrapper overhead.
- Same Ultra-Low Pricing: Maintains identical $0.14/1M input pricing with a seamless drop-in endpoint change.
Bookmark AICodeNews.com for daily coverage on open-source AI models, developer tooling benchmarks, and API pricing updates.
The official editorial desk of AICodeNews. We provide verified breaking news, in-depth tool comparisons, and hands-on technical tutorials for software engineers building with frontier and open-source AI models.
Wanna know more about us? Read here