Catch the most recent AI News
Check the most recent AI news. All that’s happening right now in the World of AI and Coding.

We curate the latest news about AI and Coding. If you love AI and Coding. Then you are gonna love our website.
-
Claude Opus 5.5 Launched: 1M Context, Always-On Thinking & 20% Price Cut
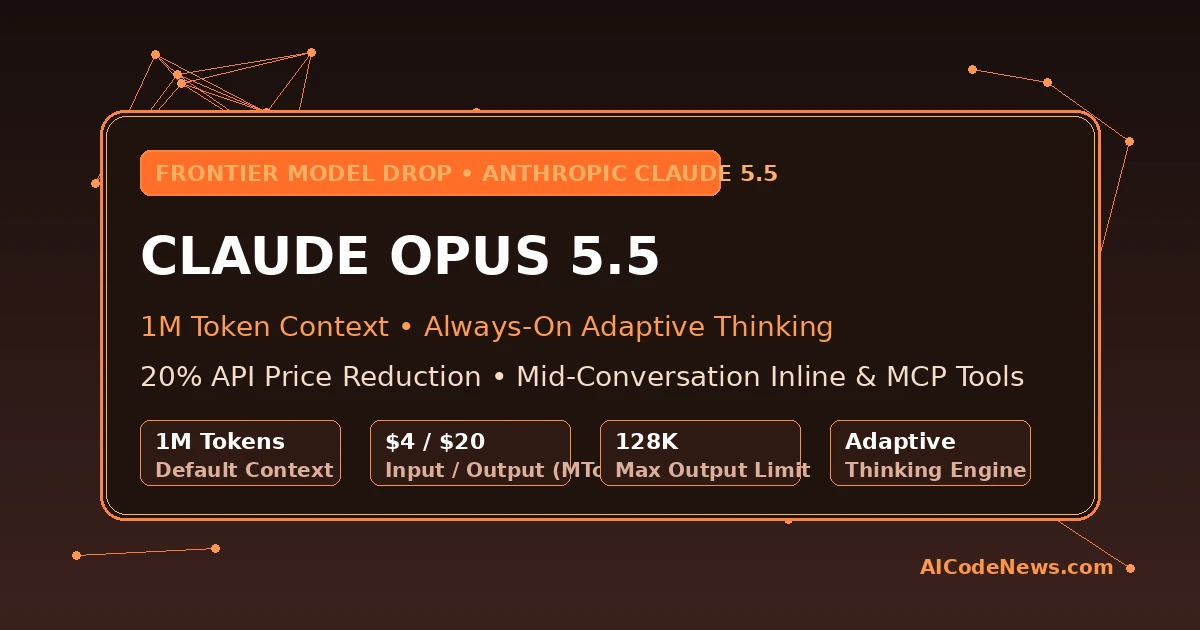
Anthropic has officially launched Claude Opus 5.5, introducing a high-performance frontier model engineered specifically for long-running agentic coding, deep research, and complex knowledge synthesis. Built with a default 1-million-token context window and 128,000 maximum output tokens, the release pairs sustained reasoning power with an immediate 20% API price reduction compared to its predecessor. The launch…
-
Qwen3.8-LiveTranslate Released: Real-Time Interleaved Speech Translation Cuts Lag to 2.3 Seconds
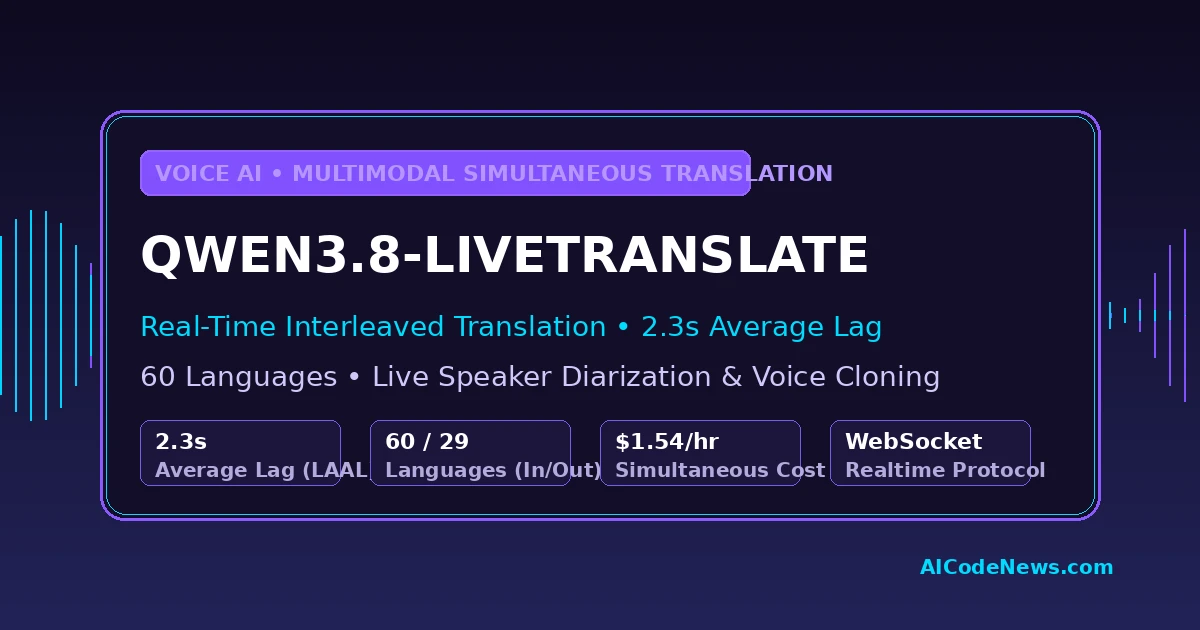
Alibaba’s Qwen team has officially released Qwen3.8-LiveTranslate, an advanced multimodal simultaneous interpretation model that listens to live speech and outputs translated audio while the speaker is still talking. By introducing an end-to-end Interleave architecture, the release drops Length-Adaptive Average Lagging (LAAL) from 2.8 seconds down to 2.3 seconds—an 18% reduction in latency across 60 supported…
-
Ternary Bonsai 2 27B Launched: 5.9GB Open-Weights LLM Retains 98% Intelligence
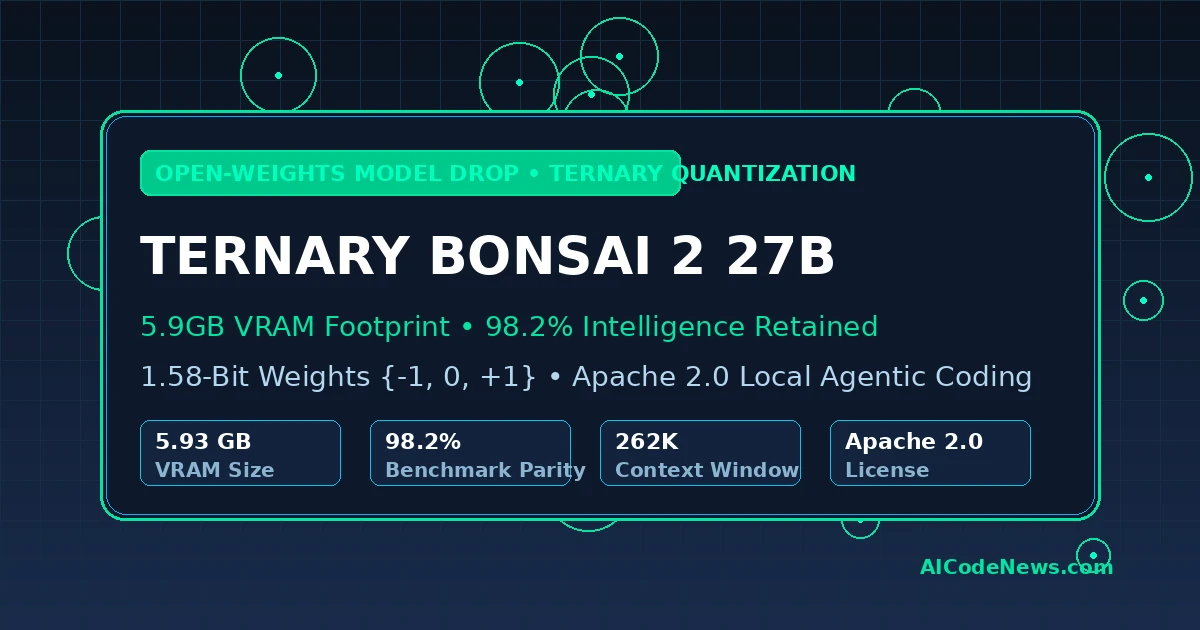
PrismML has officially released Ternary Bonsai 2 27B, a groundbreaking 5.93 GB open-weights language model that achieves 98.2% benchmark parity with full-precision 27B architectures while slashing memory footprints by 9x. The Apache 2.0-licensed release demonstrates that extreme ternary quantization {-1, 0, +1} can power complex autonomous coding agents and multimodal reasoning directly on consumer laptops…
-
TypeSafe Jev AI Launched: Decision-Only Model Delivers 70ms Latency & Free Output Tokens
Published by AICodeNews Editorial Team | September 17, 2026 Abandoning conversational text generation in favor of fast, structured software decisions, TypeSafe Jev AI has officially been unveiled by TypeSafe AI and InstructGPT co-author Diogo Almeida. Announced across official developer channels on typesafe.ai and shared by founder Diogo Almeida (@CompleteSkeptic), TypeSafe Jev AI introduces a new…
-
Cloudflare Workers Node.js Compatibility Enabled by Default: Rebuilt Module Registry for Edge AI

Published by AICodeNews Editorial Team | September 11, 2026 In a major architectural milestone that streamlines full-stack and AI agent development, Cloudflare Workers Node.js Compatibility has officially been activated by default across all serverless isolates. Announced on the official Cloudflare Blog, the upgraded Cloudflare Workers Node.js Compatibility overhaul rebuilds Workers’ internal module registry. By providing…
-
DeepSeek V4.1 Flash Launches in Beta: Native Multimodal Vision & 420 Tokens/Sec Output
Published by AICodeNews Editorial Team | September 8, 2026 In a surprise developer preview, DeepSeek V4.1 Flash has officially launched across the DeepSeek API platform under the intermediate test endpoint deepseek-v4.1-flash-expires-on-0910. Released as an invite-and-feedback evaluation preview on the official DeepSeek API Platform, DeepSeek V4.1 Flash introduces a revamped Mixture-of-Experts (MoE) architecture with native multimodal…
-
Claude Fable 5.1 and Mythos 5.1 Released: 1M Context, 75% Cheaper Cache Reads & Science SOTA
Published by AICodeNews Editorial Team | September 2, 2026 In a major frontier intelligence update for software engineering and scientific research, Claude Fable 5.1 and Mythos 5.1 have officially launched across official Anthropic developer channels. Announced on the official Anthropic Newsroom and deployed across Claude Code and the Claude Console API, Claude Fable 5.1 and…
-
OpenClaw 2.0 Releases: Guided Model Setup, 575ms Control UI & One Trust Boundary Architecture
Published by AICodeNews Editorial Team | August 31, 2026 In the biggest milestone in the project’s history, OpenClaw 2.0 has officially launched across official developer channels, delivering over 16,000 code commits and architectural overhauls built by 933 contributors. Detailed in the official announcement on OpenClaw.ai and tagged as release v2026.8.1, OpenClaw 2.0 introduces a frictionless…
-
Microduck Explained: Architecture, MuJoCo RL Training & Open-Source Biped Guide
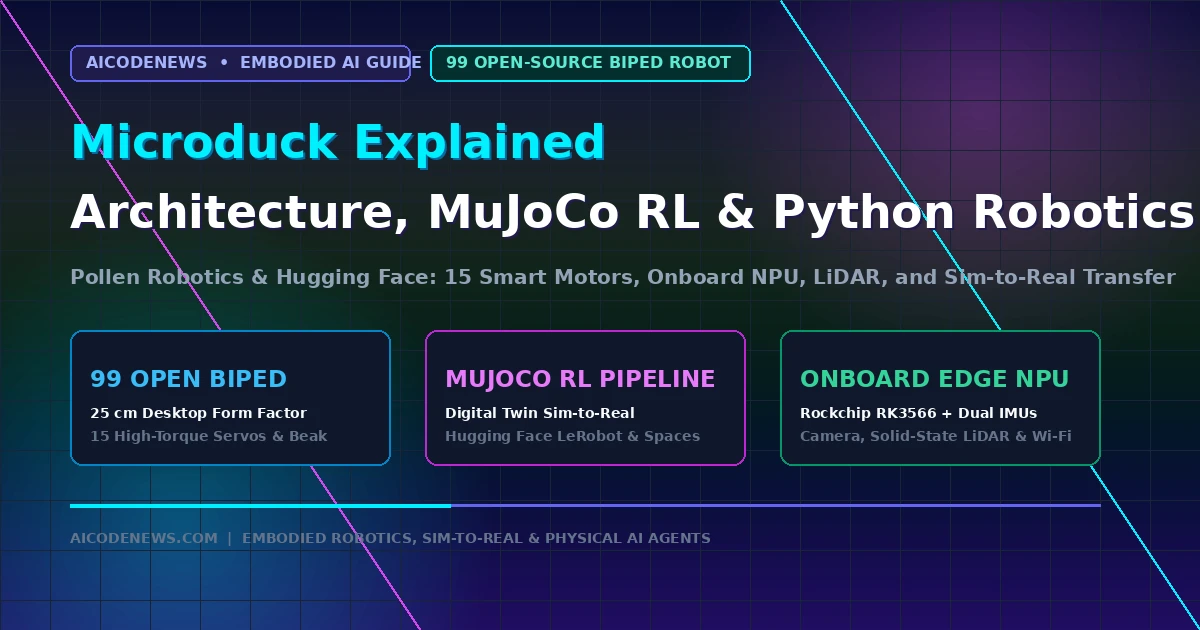
Published by AICodeNews Editorial Team | August 29, 2026 In a major breakthrough for physical AI and embodied robotics, Microduck has been officially unveiled as an open-source 25 cm biped robot co-developed by Pollen Robotics and Hugging Face. Priced at an accessible $399 and backed by full simulation environments on Hugging Face Spaces, Microduck bridges…
-
Qwen3.8-Flash-Next Launches: 125B Multimodal MoE with Multi-Token Prediction
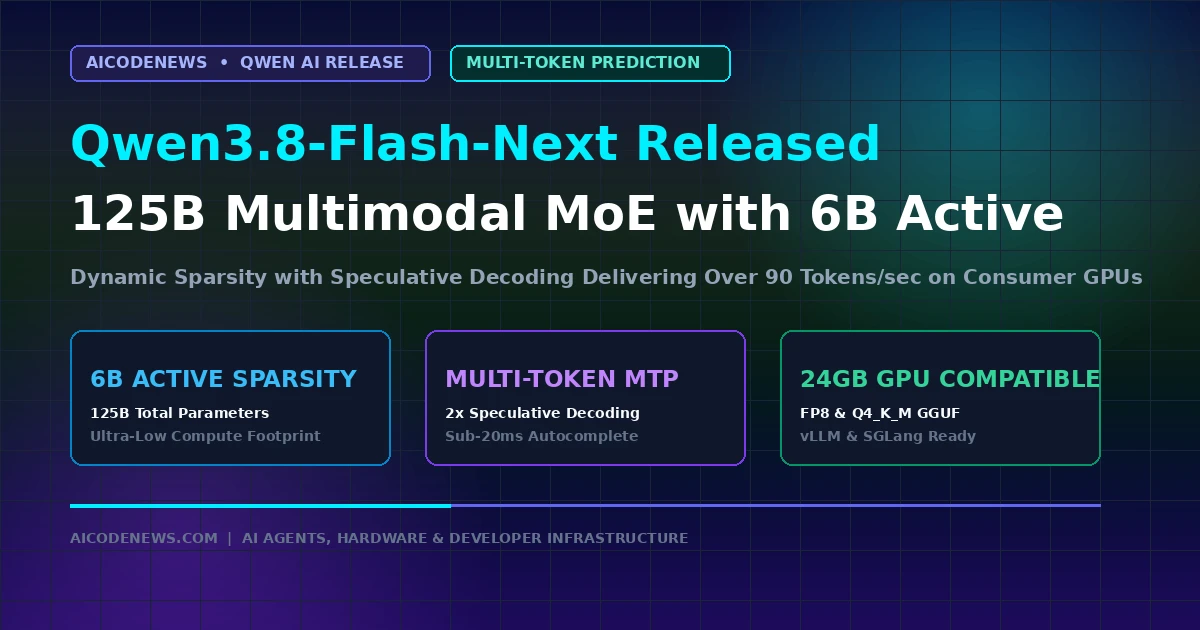
Published by AICodeNews Editorial Team | August 27, 2026 In a major open-weights release targeting high-throughput developer inference, Qwen3.8-Flash-Next has officially launched across Hugging Face and Alibaba Cloud, introducing a dynamic sparse architecture with native Multi-Token Prediction (MTP). Following twelve days after the release of Qwen 3.8-27B, Qwen 3.8-Flash-Next scales up to 125 billion total…