Published by AICodeNews Editorial Team | September 17, 2026
Abandoning conversational text generation in favor of fast, structured software decisions, TypeSafe Jev AI has officially been unveiled by TypeSafe AI and InstructGPT co-author Diogo Almeida.
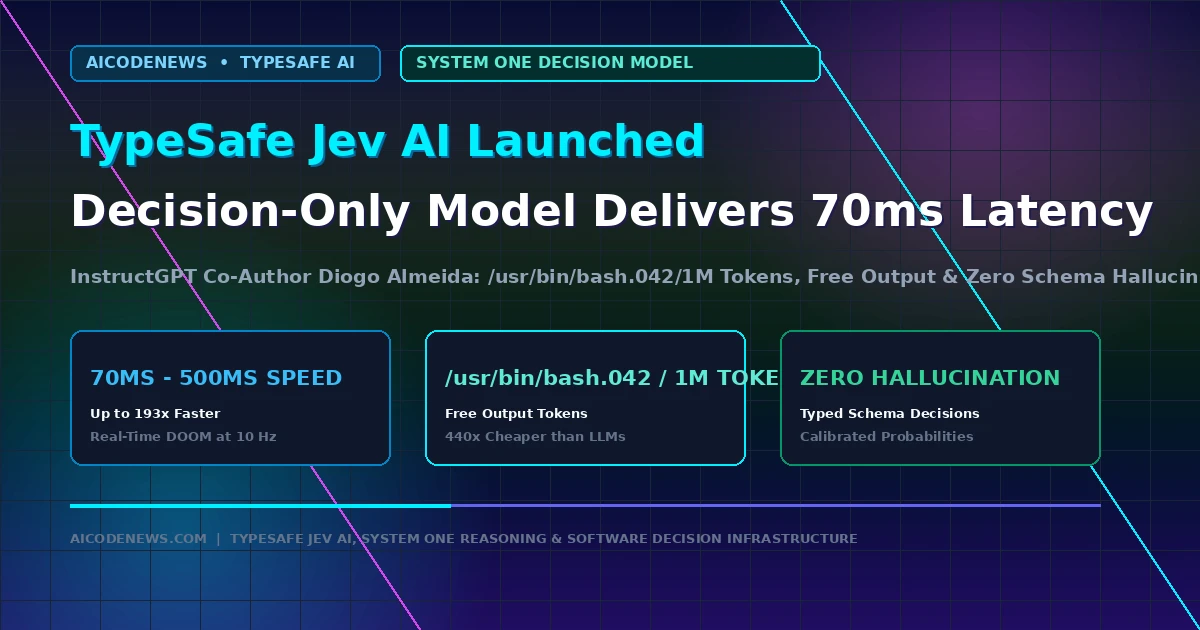
Announced across official developer channels on typesafe.ai and shared by founder Diogo Almeida (@CompleteSkeptic), TypeSafe Jev AI introduces a new model class described as “System One” AI. Instead of generating open-ended prose word-by-word, the model evaluates state data against pre-declared schemas, delivering typed decisions and calibrated probabilities in 70 to 500 milliseconds at a disruptive cost of $0.042 per million input tokens with completely free output.
1. What Is TypeSafe Jev AI?
Most production AI workflows inside software engineering do not actually need an essay; they need an instant answer to a narrow, high-frequency question: Which support queue gets this ticket? Is this database mutation safe? Should this user invoice require human review? Rather than generating paragraphs or code snippets, TypeSafe Jev AI takes two inputs: a raw state context and typed questions:
- Zero Schema Hallucination Guarantee: Because candidate outputs are strictly bound to pre-defined enums and types, the model mathematically cannot emit syntax outside your application’s schema.
- Native Probability Calibration: Every decision returns confidence scores directly sampled at the model layer, allowing engineering pipelines to send low-confidence edge cases to human review automatically.
- High-Frequency Real-Time Execution: In live demonstrations, developers ran Jev at 10 decisions per second (10 Hz) playing DOOM in real-time—executing tactical dodging and weapon switching for an entire hour for just $7.
2. Standard LLM Generation vs. TypeSafe Jev AI Architecture
The architectural trade-off replaces open-ended chatting with rapid programmatic evaluation:
| Architecture Dimension | Standard Generative LLMs (e.g. GPT-5.6 / Claude) | TypeSafe Jev AI |
|---|---|---|
| Output Mode | Auto-regressive token generation (Text/JSON) | Direct typed decision sampling |
| Inference Latency | 800ms – 3,500ms | 70ms – 500ms (Up to 193x faster) |
| Input Pricing / 1M | $2.00 – $10.00 | $0.042 (440x cheaper) |
| Output Pricing / 1M | $10.00 – $50.00 | $0.00 (Completely Free Output) |
| Hallucination Risk | Frequent string/schema format errors | Zero structural hallucination |
3. Developer Integration & Real-World Use Cases
The economic disruption of TypeSafe Jev AI is driven by its pricing structure: $0.042 per million input tokens with zero charge for output. The model is accessible via official Python and TypeScript REST SDKs, making it a drop-in replacement for triage routers, fraud classification gates, and autonomous agent routing layers.
4. Key Takeaways on TypeSafe Jev AI
- Decision-Only Shift: TypeSafe Jev AI sacrifices conversational text generation to achieve instant, typed software decisions.
- Disruptive Token Economics: $0.042/1M input pricing and free output make high-frequency background agent checks economically negligible.
- Sub-500ms Reliability: Delivers calibrated probabilities with zero structural hallucination for automated software pipelines.
Bookmark AICodeNews.com for daily updates on novel AI architectures, developer models, and inference economics.