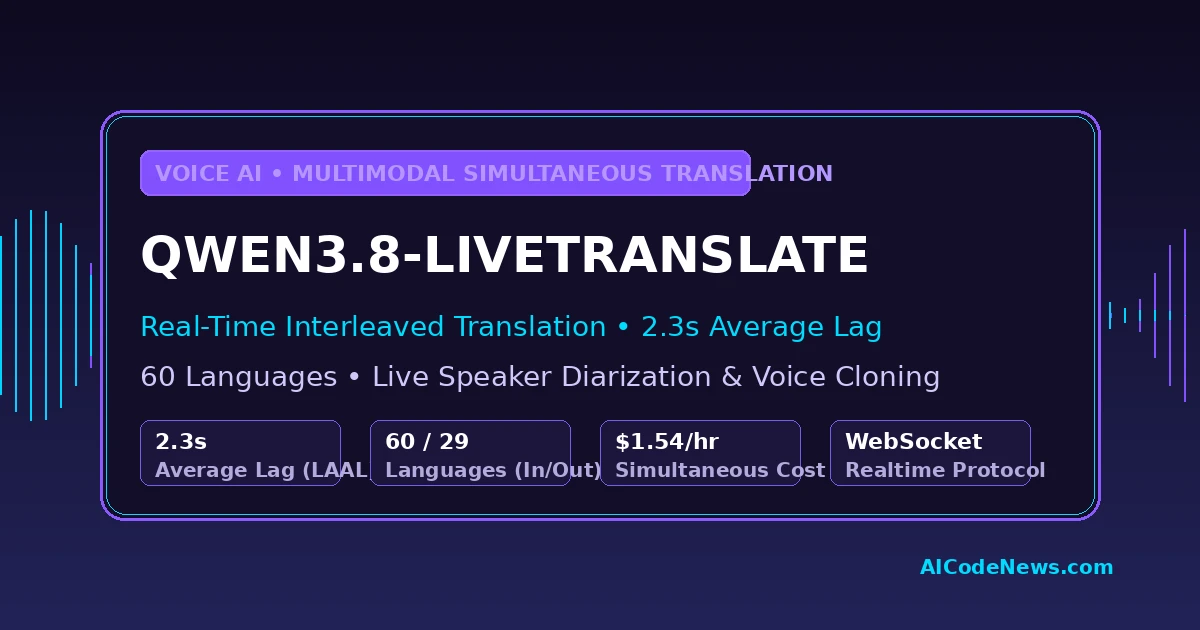
Alibaba’s Qwen team has officially released Qwen3.8-LiveTranslate, an advanced multimodal simultaneous interpretation model that listens to live speech and outputs translated audio while the speaker is still talking. By introducing an end-to-end Interleave architecture, the release drops Length-Adaptive Average Lagging (LAAL) from 2.8 seconds down to 2.3 seconds—an 18% reduction in latency across 60 supported languages.
The breakthrough bridges a critical gap in international communications, allowing global developers and enterprise teams to deploy low-latency, natural voice-to-voice translation pipelines without traditional cascading delays.
Interleaved Architecture and Latency Reductions in Qwen3.8-LiveTranslate
Traditional simultaneous translation systems rely on fragmented cascades that pass audio through independent automatic speech recognition (ASR), machine translation (MT), and text-to-speech (TTS) pipelines. The core innovation inside the new system is an Interleave streaming architecture that processes input speech, transcribed text, and target spoken audio as a single synchronized sequence.
By unifying multimodal tokens in one time-ordered stream, the engine eliminates cross-module pipeline latency. The system understands 60 input languages and provides bidirectional speech output across 29 languages, while the remaining 31 languages receive real-time streaming text translation.
| Capability / Metric | Traditional Cascaded Pipeline | LiveTranslate Architecture | Architectural Advantage |
|---|---|---|---|
| Pipeline Architecture | Decoupled ASR → MT → TTS | Unified Interleaved Multimodal Stream | Zero cross-engine serialization overhead |
| Average Lagging (LAAL) | 2.8 – 3.5 seconds | 2.3 seconds | ~18% faster real-time spoken response |
| Speaker Diarization | External diarization service | Native multi-speaker tagging | Contextual turn tracking in group meetings |
| Voice Preservation | Generic synthetic voices | Real-time zero-shot voice cloning | Maintains original speaker identity and pitch |
| Multimodal Vision Input | Audio-only transcription | Up to 2 frames/second visual context | Resolves ambiguous words using lip movements |
Speaker Diarization, Context Awareness, and Cloud Pricing
In addition to streaming latency cuts, the interpreter introduces real-time speaker diarization and automated voice preservation during multi-party calls. The system dynamically isolates distinct speakers and clones their vocal characteristics into the target spoken output, ensuring listeners immediately recognize who is speaking during multi-person conferences.
The architecture also incorporates long-context entity disambiguation, referencing historical meeting dialogue to prevent mistranslating proper nouns, brand names, and technical terms. For enterprise developers, the service is deployed as a hosted WebSocket API (livetranslate-flash-realtime) on Alibaba Cloud Model Studio and Qwen Cloud. Spoken input is billed at 7 tokens per second ($7.50/1M tokens) and spoken output at 12.5 tokens per second ($30.00/1M tokens), bringing the operational cost of one full hour of continuous bidirectional translation to approximately $1.54.
Key Takeaways for Developers
- Sub-2.5 Second Spoken Latency: Qwen3.8-LiveTranslate reduces average translation lag to 2.3 seconds using a unified Interleave architecture.
- Broad Multilingual Coverage: Ingests 60 languages with full bidirectional speech output across 29 major global languages.
- Synchronized Bilingual Streaming: Emits source transcript events alongside target audio, enabling real-time on-screen subtitle displays.
- Cost-Effective Real-Time API: Delivers production WebSocket endpoints capable of hosting continuous live interpretation for ~$1.54 per hour.
I’m Mohammed Khan, Software developer and AI researcher covering autonomous coding agents, open-source large language models, and modern developer infrastructure. Founder and lead editor at AICodeNews.
And I also build Websites using WordPress. To be honest I love WordPress and AI.
You can find more info about me here