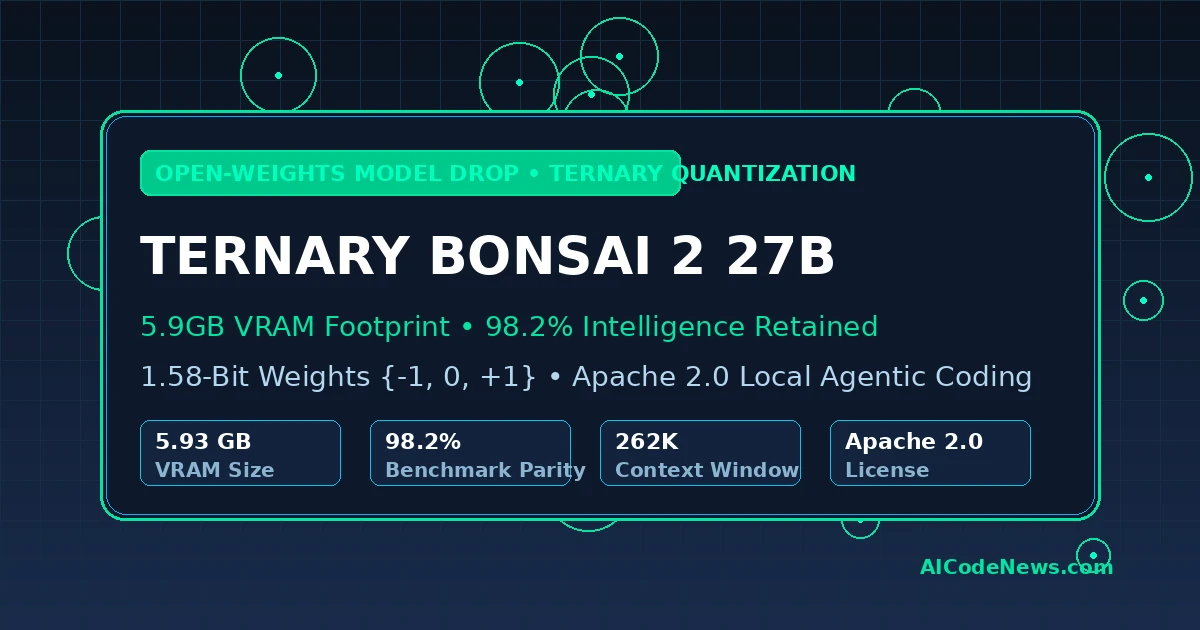
PrismML has officially released Ternary Bonsai 2 27B, a groundbreaking 5.93 GB open-weights language model that achieves 98.2% benchmark parity with full-precision 27B architectures while slashing memory footprints by 9x. The Apache 2.0-licensed release demonstrates that extreme ternary quantization {-1, 0, +1} can power complex autonomous coding agents and multimodal reasoning directly on consumer laptops and single GPUs.
The release marks a pivotal moment for on-device computing, proving that developers no longer need dual RTX 4090s or quantized FP8 compromises to execute 27B-class models locally.
Core Architectural Breakdown of Ternary Bonsai 2 27B
Built upon Alibaba’s open-weights Qwen 27B architecture, the engineering behind the Bonsai 2 system replaces standard 16-bit floating-point weight representations with ternary {-1, 0, +1} values. This allows matrix multiplication operations to be executed primarily through energy-efficient additions and subtractions rather than compute-heavy floating-point MACs.
The model occupies only 5.93 GB of disk and VRAM, compared to 53.80 GB in standard FP16. Unlike post-training quantization methods that often degrade coherence in reasoning tasks, PrismML pre-trains and aligns the ternary weights directly with FP16 group scalers, enabling unprecedented intelligence retention across multi-step tasks.
| Specification | Standard FP16 Baseline (27B) | Bonsai 2 (Ternary Quantized) | Efficiency Multiplier |
|---|---|---|---|
| Model Size / VRAM Footprint | 53.80 GB | 5.93 GB | 9.07x Reduction |
| Arithmetic Precision | 16-bit Floating Point | 1.58-bit Ternary {-1, 0, +1} | ~10x Parameter Compression |
| Context Window | 128K tokens | 262K tokens | 2x Context Window |
| Hardware Minimum | 2x 32GB GPUs or Cloud Pod | 16GB Laptop / Single 24GB GPU | Edge-Deployable |
| License | Permissive Open Weights | Apache 2.0 | Full Commercial Use |
Benchmark Parity and Agentic Coding Performance
Across a comprehensive suite of 20 recognized evaluation benchmarks, the model retains 98.2% of its parent model’s unquantized scores. In agentic code generation and long-horizon tool orchestration, the model successfully drove autonomous coding workflows inside Cline and native terminal shells without degrading into syntax loops.
The architecture also retains native multimodal capabilities, allowing local developers to process image inputs, architectural diagrams, and terminal snapshots within an expansive 262,144-token context window. The engineering team has published optimized GGUF binaries for standard llama.cpp runtimes alongside dedicated 2-bit MLX kernels tailored for Apple Silicon Unified Memory architectures.
Open-weights releases of this caliber demonstrate that the memory wall in consumer AI is crumbling. By combining ternary representations with scalable post-training techniques, developers can now run production-grade autonomous agent loops entirely air-gapped on existing hardware.
Key Takeaways for Developers
- Massive Footprint Compression: Ternary Bonsai 2 27B shrinks a 27B-parameter architecture to 5.93 GB, fitting comfortably within 16 GB MacBook Unified Memory or an RTX 4070.
- Near-Zero Precision Loss: Delivers 98.2% average benchmark retention across 20 evaluations, maintaining reasoning integrity in math and coding benchmarks.
- Expanded Native Context: Features a 262K-token context window, supporting full-codebase ingestion and persistent agentic memory.
- Immediate Ecosystem Integration: Apache 2.0 weights are available immediately via Hugging Face with native support for llama.cpp and MLX.