Category: Latest AI News

  • GLM-5.3-Flash Launches: 320B Hybrid MoE Architecture with Sub-$0.15 Token Pricing

    GLM-5.3-Flash Launches: 320B Hybrid MoE Architecture with Sub-$0.15 Token Pricing

    Published by AICodeNews Editorial Team | August 26, 2026

    In a major breakthrough for high-throughput developer inference, GLM-5.3-Flash has officially launched, delivering frontier-class reasoning and coding intelligence at a fraction of standard API costs.

    Announced across developer channels on Z.ai and released as open weights on Hugging Face, GLM-5.3-Flash introduces a hybrid sparse-linear attention architecture that cuts inference Key-Value (KV) cache memory by over 4.4x while maintaining a massive 1-million-token context window.

    1. Core Architecture & Performance Benchmarks of GLM-5.3-Flash
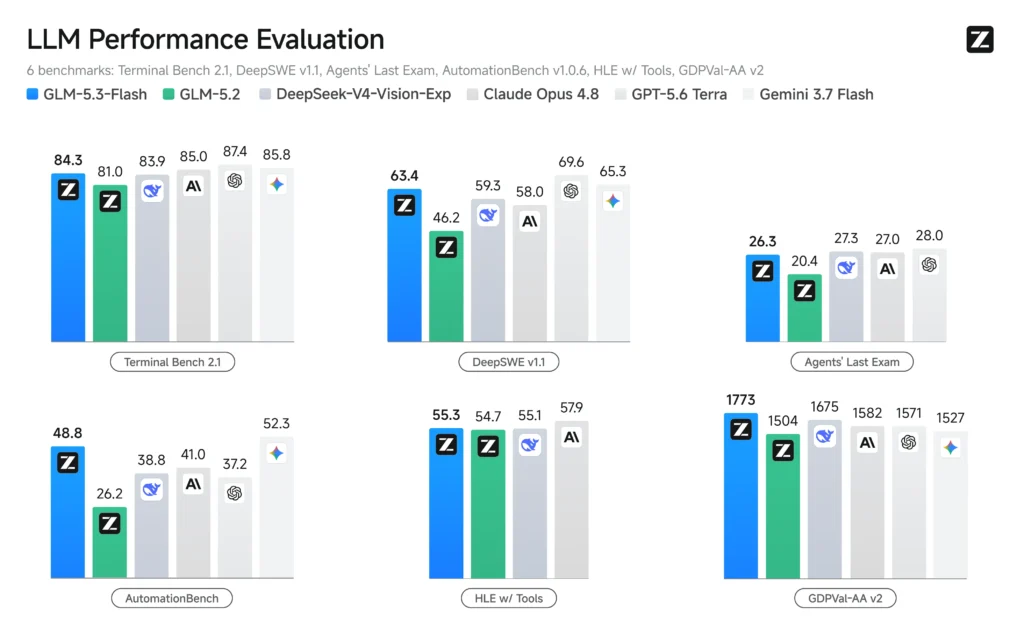
    glm 5.3 flash benchmarks

    Under the hood, GLM-5.3-Flash features a 320-billion total parameter Mixture-of-Experts (MoE) design with only 18 billion active parameters per token. This dynamic sparsity delivers rapid generation speeds exceeding 43 tokens per second:

    • Hybrid Attention Mechanism: Combines sparse windowed attention with linear recurrent attention, reducing compute overhead by 3.01x and KV cache size by 4.44x compared to base GLM-5.3.
    • 1M Context & 128k Output Window: Supports 1,048,576 input tokens and up to 131,072 completion tokens, making it ideal for whole-repository refactoring and autonomous debugging loops.
    • Frontier Benchmark Scores: Achieves a 57+ rating on the Artificial Analysis Intelligence Index, outperforming comparable lightweight models on multi-file coding and mathematical problem-solving.

    2. API Pricing & Token Economics of GLM-5.3-Flash

    The defining advantage of GLM 5.3-Flash is its aggressive pricing structure, positioning it as one of the most cost-effective reasoning endpoints in the industry:

    Model EndpointInput Price / 1MCached Input / 1MOutput Price / 1MContext Window
    GLM-5.3-Flash (Launch Rate)$0.075 – $0.15$0.015 – $0.03$0.20 – $0.391,048,576 Tokens
    DeepSeek-V4-Flash$0.14$0.028$0.281,048,576 Tokens
    Gemini 3.7 Flash$0.15$0.0375$0.601,048,576 Tokens
    GLM-5.3 (Flagship Base)$1.40$0.26$4.401,048,576 Tokens

    3. Developer Integration: Python API & Tool Calling with GLM 5.3-Flash

    GLM 5.3-Flash provides full drop-in compatibility with the OpenAI SDK, supporting native function calling, Model Context Protocol (MCP) tool execution, and structured JSON outputs:

    from openai import OpenAI
    
    # Initialize the client pointing to the Z.ai endpoint
    client = OpenAI(
        api_key="YOUR_ZAI_API_KEY",
        base_url="https://api.z.ai/v1"
    )
    
    # Stream code generation with GLM-5.3-Flash
    response = client.chat.completions.create(
        model="glm-5.3-flash",
        messages=[
            {"role": "system", "content": "You are an expert Python software engineer."},
            {"role": "user", "content": "Write a high-throughput async queue worker using asyncio and Redis."}
        ],
        temperature=0.2,
        stream=True
    )
    
    for chunk in response:
        if chunk.choices[0].delta.content:
            print(chunk.choices[0].delta.content, end="")

    4. Key Takeaways

    • 320B Hybrid MoE Architecture: GLM-5.3-Flash activates 18B parameters per token, cutting KV cache VRAM requirements by 4.44x.
    • Ultra-Low Token Pricing: Offers input pricing starting at $0.075/1M tokens, reducing agent operating costs by over 90% compared to dense flagship models.
    • Seamless Drop-In API: Compatible with OpenAI SDKs, OpenRouter, Cursor, Claude Code, and native MCP servers.

    Bookmark AICodeNews.com for daily updates on open-weight model releases, API pricing benchmarks, and AI developer infrastructure.
  • Nvidia NemoClaw OpenClaw Gateway: Enterprise Multi-Channel Integration for Autonomous Agents

    Nvidia NemoClaw OpenClaw Gateway: Enterprise Multi-Channel Integration for Autonomous Agents

    Published by AICodeNews Editorial Team | August 25, 2026

    In a major enterprise expansion for open-source autonomous agents, the Nvidia NemoClaw OpenClaw Gateway has officially launched to connect OpenClaw runtimes directly with enterprise communication channels and GPU hardware backends.

    Documented in the latest Nvidia Developer Release Notes, the Nvidia NemoClaw OpenClaw Gateway enables corporate software teams to orchestrate 24/7 personal and team AI workers across Microsoft Teams, Slack, and internal enterprise webhooks.

    1. Core Capabilities of the Nvidia NemoClaw OpenClaw Gateway

    The Nvidia NemoClaw OpenClaw Gateway pairs the viral OpenClaw SKILL.md architecture with enterprise security and hardware acceleration:

    • Microsoft Teams & Enterprise Slack Integration: Seamlessly routes multi-turn agent conversations, code review requests, and server alerts through encrypted corporate chat channels.
    • TensorRT-LLM Hardware Acceleration: Connects agent execution directly to Nvidia NeMo inference microservices, reducing tool-calling latency by over 50%.
    • Granular Role-Based Access Control (RBAC): Restricts what bash tools, database connectors, and cloud APIs the agent can invoke based on corporate identity tiers.

    2. Simplified Enterprise Deployment

    Setting up the Nvidia NemoClaw OpenClaw Gateway is streamlined via native containerized blueprints:

    • One-Command Docker Compose: Deploy pre-configured gateway images linking local GPU hardware to corporate authentication providers in minutes.
    • Audit Logging & Compliance: Records all tool invocations and terminal commands to immutable local logs to satisfy enterprise compliance standards.

    3. Key Takeaways

    • Enterprise Messaging Bridge: Nvidia NemoClaw OpenClaw Gateway connects OpenClaw AI to Microsoft Teams and Slack.
    • Hardware Optimized: Built-in acceleration for Nvidia TensorRT-LLM and NeMo microservices.
    • Production Security: Role-based permissions, automated credential rotation, and full audit logging.

    Follow AICodeNews.com for daily coverage on autonomous agent runtimes, enterprise tooling, and GPU infrastructure.

  • Nvidia Nemotron Poolside Partnership

    Nvidia Nemotron Poolside Partnership

    Nvidia Nemotron Poolside Partnership: $1B Investment to Accelerate Open-Source Coding Models

    Published by AICodeNews Editorial Team | August 24, 2026

    In a major push to expand the open-weights software engineering ecosystem, the Nvidia Nemotron Poolside partnership has been announced, backed by a $1 billion investment at a $12 billion valuation.

    As part of the collaboration, over 100 dedicated AI engineers from Poolside are joining the Nvidia Nemotron Poolside initiative to accelerate open-source foundation models that offer lower inference latency, reduced operating costs, and deeper customization than closed API endpoints.

    1. Why the Nvidia Nemotron Poolside Partnership Accelerates Open-Weights AI

    The Nvidia Nemotron Poolside collaboration pairs specialized code-generation datasets with hardware-level compiler optimizations:

    • Specialized Software Datasets: Poolside’s repository-scale code intelligence and execution-guided reinforcement learning (RL) pipelines feed directly into Nvidia’s Nemotron training runs.
    • Deep CUDA & TensorRT-LLM Integration: Co-designing models with hardware engineers ensures optimal kernel execution, custom FP8/NVFP4 quantizations, and maximized tokens-per-second on Blackwell and Hopper architectures.
    • Enterprise Customizability: Providing open-weight architectures that software teams can fine-tune on private internal codebases without leaking proprietary IP to third-party cloud APIs.

    2. Technical Architecture & Developer Economics

    Here is how the Nvidia Nemotron Poolside open architecture compares to proprietary closed-source coding APIs:

    Architectural DimensionProprietary Closed EndpointsNvidia Nemotron & Poolside Open Stack 
    Deployment FlexibilityVendor-hosted cloud API onlySelf-hosted on-prem, private VPC, or local workstation
    Kernel-Level OptimizationStandard cloud abstractionNative TensorRT-LLM and custom CUDA kernel acceleration
    Codebase Privacy & Data ControlSubject to remote data retention policies100% on-premises execution with zero telemetry leaks
    Inference Cost at ScaleLinear per-token cloud API billingFixed infrastructure hardware compute costs

    3. Developer Impact: Local Deployment & Agent Workflows

    By bringing over 100 specialized coding engineers into the Nemotron fold, the Nvidia Nemotron Poolside initiative aims to deliver enterprise-grade SWE-bench performance across both multi-billion parameter cloud deployments and quantized local developer tools:

    • Hybrid Mamba-Transformer Scaling: Expanding on Nemotron’s hybrid linear attention layers to handle massive 1M+ token multi-repo context windows with near-constant memory footprint.
    • Native MCP Server Compatibility: Out-of-the-box tool calling for Model Context Protocol (MCP) servers, terminal CLI workflows, and in-editor background IDE agents.

    4. Key Takeaways on the Nvidia Nemotron Poolside Partnership

    • $1B Strategic Investment: The Nvidia Nemotron Poolside alliance invests $1B at a $12B valuation to challenge closed coding models.
    • 100+ Engineering Transfer: Deepens technical collaboration on open-weight code generation and execution-guided RL.
    • Hardware-Optimized Open Weights: Delivers customizable, high-throughput models engineered natively for CUDA and TensorRT-LLM.

    Bookmark AICodeNews.com for daily updates on open-weight AI architectures, developer benchmarks, and infrastructure news.

  • Ornith 1.5 Releases on Hugging Face: MIT Open-Weights with Self-Improving GRPO Loop

    Ornith 1.5 Releases on Hugging Face: MIT Open-Weights with Self-Improving GRPO Loop

    Published by AICodeNews Editorial Team | August 22, 2026

    In a major milestone for open-weights artificial intelligence, Ornith 1.5 has officially launched on Hugging Face under the permissive MIT license, introducing an end-to-end autonomous self-improvement architecture that systematically expands its own training curriculum.

    Developed as a continuation of Ornith-1.0 on top of Qwen 3.5 and Gemma 4 architectures, the Ornith 1.5 suite spans three distinct parameter scales (397B MoE, 35B MoE, and 9B Dense), delivering frontier-class reasoning and coding performance without closed API lock-in.

    1. Three Production Scales of Ornith 1.5

    The Ornith 1.5 family is architected to address diverse compute and deployment environments:

    • Ornith-1.5-397B MoE (Flagship Scale): Designed for heavy-duty reasoning, autonomous coding, and multi-agent systems, scoring 86.0% on SWE-bench Verified and 86.1 on Terminal-Bench 2.1.
    • Ornith-1.5-35B MoE (Mid-Scale Efficiency): Activates only 3 billion parameters per token, delivering 79.0% on SWE-bench Verified while cutting inference costs by over 80%.
    • Ornith-1.5-9B Dense (Edge & Mobile Scale): Compact model compressible down to a 1.5 GB footprint for native local execution on iPhones, iPads, and consumer Mac/Android hardware.

    2. Benchmark Breakdown: How Ornith-1.5 Compares to Claude and DeepSeek

    Independent evaluation suites show Ornith-1.5 setting new open-source standards across coding, terminal navigation, and scientific reasoning:

    ModelTerminal-Bench 2.1SWE-bench VerifiedGPQA DiamondBrowseComp 
    Ornith 1.5-397B MoE86.186.0%92.8%86.6%
    Claude Opus 4.885.085.8%——
    DeepSeek-V4-Flash82.781.6%——
    GLM-5.281.0———
    Ornith 1.5-35B MoE (3B Active)68.579.0%——
    Ornith 1.5-9B Dense (1.5 GB Mobile)46.270.6%86.4%—

    3. Under the Hood: Autonomous Task Generation and GRPO Optimization

    Unlike traditional language models trained on static human-curated datasets, Ornith 1.5 utilizes a continuous three-stage self-improvement loop:

    • Stage 1 (Frontier Task Generation): The model proposes progressively harder tasks that expose its own reasoning gaps, optimized via a Task Reward (R_task) evaluating validity, frontier difficulty (targeting a 20% empirical success rate), and novelty.
    • Stage 2 (Dynamic Scaffold Construction): The system designs customized evaluation harnesses and toolsets for each generated problem, rewarded for alignment and resistance to reward hacking.
    • Stage 3 (Group Relative Policy Optimization): Using GRPO, the policy jointly optimizes task generation, scaffold design, and solution rollouts within the same training loop, yielding compounding capability gains over time.

    4. Quantization, Formats & Open Availability

    The entire Ornith 1.5 model suite is immediately available on Hugging Face under the MIT License:

    • Quantized Formats: Published in official FP8, GGUF, MLX, and NVFP4 formats for instant deployment on vLLM, SGLang, Ollama, and Apple Silicon.
    • Zero Server Dependencies: The 9B model can be deployed completely offline on consumer mobile devices with sub-50ms latency.

    5. Key Takeaways on Ornith 1.5

    • Autonomous Self-Improvement: Ornith 1.5 continuously expands its capability frontier through joint task generation and GRPO optimization.
    • SOTA Open Performance: The 397B MoE flagship surpasses Claude Opus 4.8 on SWE-bench Verified (86.0%) and Terminal-Bench (86.1).
    • Full MIT Open Weights: Available immediately across 397B, 35B, and 9B parameter scales on Hugging Face.

    Bookmark AICodeNews.com for daily updates on open-weight foundation models, LLM benchmarks, and AI developer infrastructure.

  • DeepSeek-V4-Flash-Vision-Exp Launches: Multimodal Vision Reasoning & Free Files API

    DeepSeek-V4-Flash-Vision-Exp Launches: Multimodal Vision Reasoning & Free Files API

    Published by AICodeNews Editorial Team | August 21, 2026

    In a major multimodal upgrade to its low-cost model lineup, DeepSeek has officially released DeepSeek-V4-Flash-Vision-Exp, adding high-speed visual reasoning and chart analysis while matching the full text and coding performance of the base V4-Flash model.

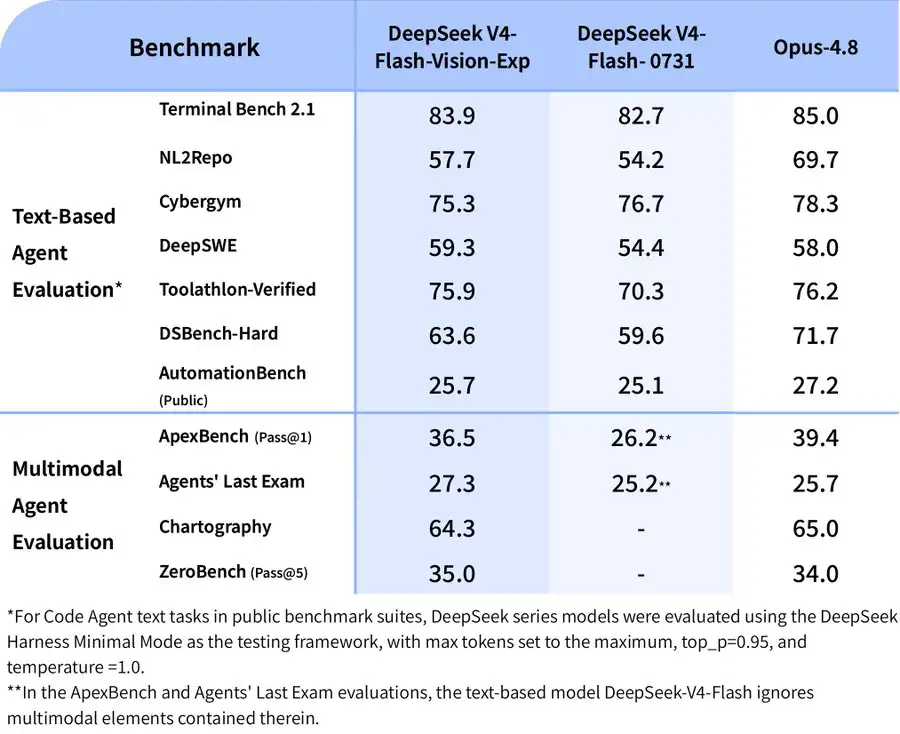
    Announced directly on the official DeepSeek API Platform, DeepSeek-V4-Flash-Vision-Exp elevates open-weights multimodal agent performance, closing the capability gap with closed models on benchmark suites like Terminal Bench (83.9) and ApexBench (36.5).

    1. Multimodal Benchmarks & Vision Capabilities for DeepSeek-V4-Flash-Vision-Exp

    DeepSeek-V4-Flash-Vision-Exp benchmarks

    While previous lightweight vision models struggled with dense UI layouts and technical schematics, DeepSeek-V4-Flash-Vision-Exp is engineered for autonomous agent computer use and document parsing:

    • Terminal Bench Score (83.9): Excels at interpreting CLI terminal outputs, error stack traces, and multi-window developer workflows.
    • ApexBench Visual Accuracy (36.5): High precision in extracting data from multi-column PDF tables, system architecture flowcharts, and financial charts.
    • Zero Compromise on Text & Code: Retains 100% of the reasoning, coding logic, and world knowledge of the standard V4-Flash model.

    2. API Architecture, 384-Token Pricing & The New Files API

    Developers can begin using DeepSeek-V4-Flash-Vision-Exp immediately across production developer endpoints using standard Chat Completions, Messages, and Responses APIs:

    Feature / ParameterSpecification / Capability 
    Model Identifierdeepseek-v4-flash-vision-exp
    Image Tokenization & PricingCapped at max 384 tokens per image at standard V4-Flash pricing rates
    Input FormatsMixed text + image via Base64, external image URLs, or the new Files API
    New Files API100% Free: Upload an image once, reference by file_id to save request payload bandwidth
    Ecosystem SupportDay-one support in DeepSeek Harness 0.1.1, OpenCode, and OpenRouter

    The companion release of DeepSeek Harness 0.1.1 provides out-of-the-box support, allowing autonomous agents to stream visual desktop frames and inspect local code artifacts without manual token chunking.

    3. Key Takeaways on DeepSeek-V4-Flash-Vision-Exp

    • Experimental Multimodal Release: DeepSeek-V4-Flash-Vision-Exp brings image comprehension to the low-cost V4-Flash tier.
    • Predictable Image Billing: Flat 384-token billing cap per image makes high-volume visual agent pipelines economical.
    • Free Files API: Eliminates redundant image re-uploads by referencing persistent file IDs across multi-turn chat sessions.

    Bookmark AICodeNews.com for daily coverage on multimodal AI models, agent frameworks, and developer API releases.

  • Cloudflare Browser Run Limits Expanded: High-Concurrency Headless Isolates for AI Agents

    Cloudflare Browser Run Limits Expanded: High-Concurrency Headless Isolates for AI Agents

    Published by AICodeNews Editorial Team | August 21, 2026

    To support enterprise autonomous web agents and large-scale data extraction pipelines, Cloudflare Browser Run Limits have officially expanded across Cloudflare’s global edge network.

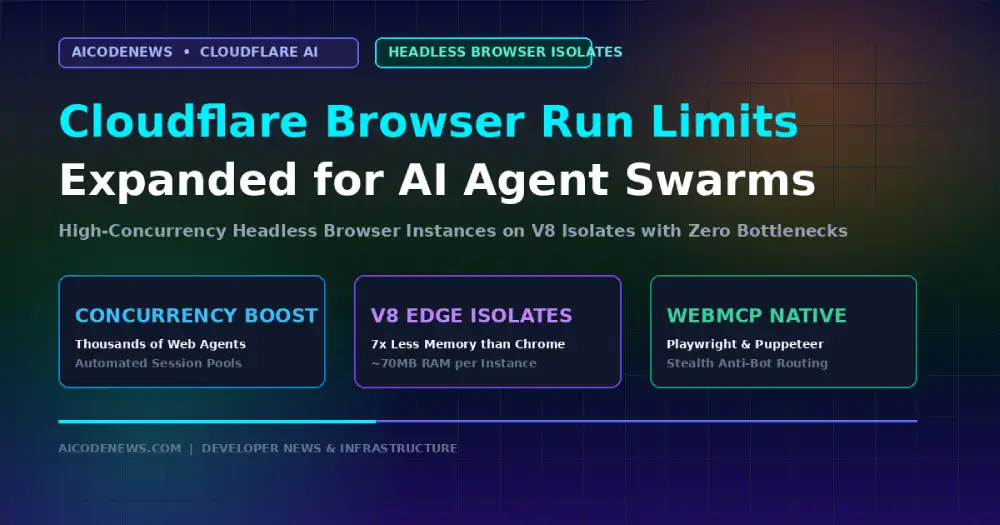
    Announced on the official Cloudflare Changelog, the expanded Cloudflare Browser Run Limits allow developers to spin up thousands of concurrent headless browser instances inside lightweight V8 isolates with automated session pooling.

    1. Why Cloudflare Browser Run Limits Were Upgraded

    As autonomous AI agents shift from passive text completion to active web operations (form-filling, UI testing, competitive price monitoring), legacy headless browser limits created infrastructure bottlenecks:

    • High-Density Concurrency Scaling: The expanded Browser Run Limits enable enterprise accounts to run parallel browser swarms without experiencing connection queue timeouts.
    • Optimized Kitesurf Integration: Built to complement Cloudflare’s newly released Kitesurf browser engine, reducing memory overhead to ~70MB per active agent instance.
    • Session Persistence & Anti-Bot Stealth: Includes native cookie synchronization and residential IP routing to prevent AI agents from triggering CAPTCHA blocks during automated data ingestion.

    2. Developer Provisioning for Cloudflare Browser Run Limits

    Taking advantage of the new Cloudflare Browser Run Limits is streamlined for existing Cloudflare Workers developers:

    • Dashboard & API Quota Requests: Teams requiring custom enterprise concurrency thresholds can request instant limit increases directly through the Cloudflare developer dashboard.
    • Standard Playwright & Puppeteer Compatibility: Connect existing agent automation scripts using standard WebSocket endpoints with zero code refactoring.

    3. Key Takeaways

    • Massive Concurrency Boost: Cloudflare Browser Run Limits expanded to handle high-frequency autonomous agent browser swarms.
    • V8 Edge Efficiency: Runs in lightweight isolates, cutting server RAM consumption by up to 7x compared to standard Chromium.
    • Zero-Config Tool Integration: Native support for WebMCP, Playwright, and Puppeteer agent connectors.

    Follow AICodeNews.com for daily updates on cloud edge computing, browser automation, and AI developer infrastructure.

  • Cloudflare Workers Access AI: Unified Zero Trust Controls for Agent Gateways

    Cloudflare Workers Access AI: Unified Zero Trust Controls for Agent Gateways

    As developers deploy autonomous coding agents and Model Context Protocol (MCP) servers across distributed serverless infrastructure, Cloudflare Workers Access AI has officially rolled out to provide unified identity verification, private-by-default routing, and edge security policies.

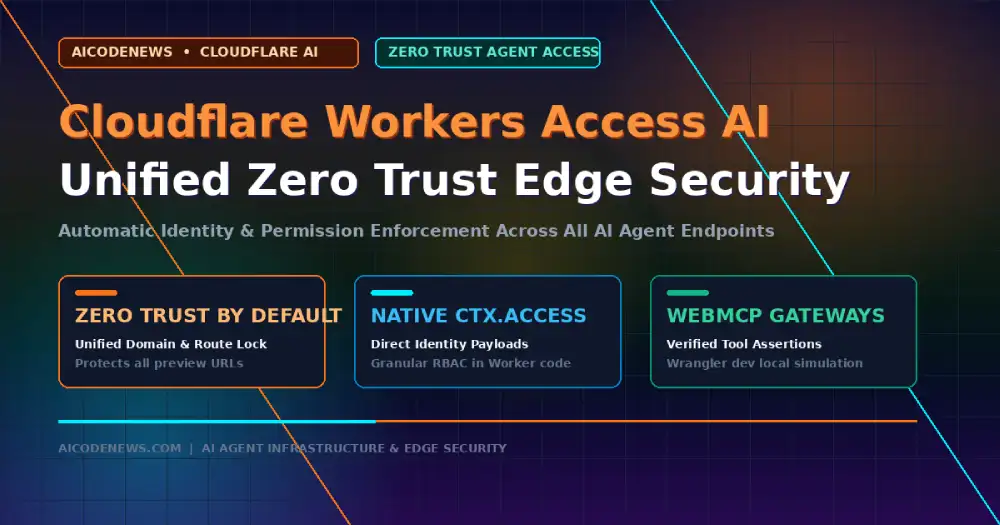
    Announced on the Cloudflare Changelog, Cloudflare Workers Access AI eliminates the need to manually configure access rules across separate routes and custom domains, automatically attaching Zero Trust policies directly to the underlying Worker.

    1. Why Cloudflare Workers Access AI Matters for Agent Gateways

    Securing autonomous agent endpoints and internal database connectors has historically required complex middleware layers:

    • Unified Multi-Domain Protection: With Cloudflare Workers Access AI, an application reachable on a custom domain, standard route, and workers.dev preview URL is protected simultaneously under a single attached policy.
    • Private by Default Architecture: Engineering teams can enforce global rules where all newly created Workers require identity authentication before receiving incoming agent traffic.
    • Native Context Identity (ctx.access): Developers can access user and service identity payloads directly inside Worker code to enforce granular role-based access control (RBAC).

    2. Local Testing & WebMCP Integration with Cloudflare Workers Access AI

    To ensure developer velocity remains uninterrupted, Cloudflare Workers Access AI includes deep tooling integration for existing serverless workflows:

    • Local wrangler dev Simulation: Test authenticated agent handoffs and token payloads locally before deploying to global edge nodes.
    • Automated WebMCP Gateways: Safely expose internal microservices as verified Model Context Protocol endpoints with cryptographic identity assertions.

    3. Key Takeaways

    • Zero Trust by Default: Cloudflare Workers Access AI locks down agent endpoints across all custom domains and preview URLs.
    • Native Context Access: Inspect identity claims inside ctx.access with zero latency overhead.
    • Streamlined Security: Eliminates manual route tracking and protects internal AI tools automatically.

    Follow AICodeNews.com for daily updates on AI agent infrastructure, edge computing, and developer security tooling.

  • DeepSeek Releases DeepSeek Harness: Open-Source Agent Runtime Reaches 144K GitHub Stars

    DeepSeek Releases DeepSeek Harness: Open-Source Agent Runtime Reaches 144K GitHub Stars

    In a major open-source release reshaping autonomous software development, DeepSeek AI has launched DeepSeek Harness, a fully modular agent execution runtime that has surged past 144,000 stars on GitHub within days of release.

    Available as a developer preview on the official DeepSeek GitHub Repository, DeepSeek Harness takes a radical architectural stance: it is not a language model, but the complete operational layer around one—orchestrating terminal commands, permissions, memory, tool pipelines, and decision-making loops.

    1. The Core Philosophy of DeepSeek Harness: Everything Is a Plugin

    Where proprietary agent tools treat the execution loop as a protected black box, this architecture eliminates the concept of a privileged core:

    • 100% Swappable Components: In this runtime, every single capability—from model adapters and sandbox environments to session storage and the decision loop itself—is a self-contained plugin.
    • Extend Without Forking: Developers can introduce entirely new agentic behaviors by mounting custom plugins rather than maintaining complex project forks.
    • Model-Agnostic Freedom: Released under the permissive MIT license, the framework connects seamlessly to DeepSeek endpoints, local Ollama/vLLM instances, or any OpenAI-compatible API.

    2. Theoretical Grounding: Cordis Meta-Framework & Formal Proofs

    Unlike typical wrapper frameworks, DeepSeek Harness is built on Cordis, a composition meta-framework backed by an 88-page academic research paper co-authored by Peking University and DeepSeek researchers:

    • Formally Verified Self-Modification: The underlying mathematical proofs demonstrate that an autonomous program can safely rewrite its own execution graph and plugin stack at runtime without causing system deadlocks.
    • Reversible Lifecycle Effects: Every plugin registration is treated as an isolated state effect that safely unwinds whenever a component is detached or reloaded.

    3. Developer Availability & Getting Started

    Developers can launch the DeepSeek Harness developer preview and explore its built-in browser interface with a single terminal command:# Launch the DeepSeek Harness local web interface on port 3080

    npx @deepseek-ai/dsh web

    DeepSeek noted that because the release is currently in active developer preview, rapid iteration and architectural breaking changes are expected as the community ecosystem matures.

    4. Key Takeaways

    • Viral Open-Source Release: DeepSeek Harness surpasses 144K GitHub stars under the MIT license.
    • Everything Is a Plugin: Model adapters, tools, sandboxes, and agent loops are 100% modular and replaceable.
    • Formal Theory Under the Hood: Built on Cordis and formal self-rewriting program proofs from Peking University and DeepSeek.

    Bookmark AICodeNews.com for daily updates on open-source agent runtimes, model pricing, and developer tools.

  • Stripe Acquires OpenRouter in $7B+ Deal to Power the AI Agent Economy

    Stripe Acquires OpenRouter in $7B+ Deal to Power the AI Agent Economy

    Published by AICodeNews Editorial Team | August 17, 2026

    In a landmark deal reshaping developer AI infrastructure, fintech giant Stripe Acquires OpenRouter for more than $7 billion to establish the dominant routing and financial layer for autonomous software agents.

    The news that Stripe Acquires OpenRouter represents the largest infrastructure acquisition in AI history, uniting OpenRouter’s developer gateway of over 400 models with Stripe’s global payments and metering rails.

    1. Why Stripe Acquires OpenRouter: Controlling the Inference Tollgate

    Over the past two years, OpenRouter quietly became the default API gateway for more than 8 million developers and coding tools:

    • Unified Multi-Model Gateway: Developers access Claude, GPT, DeepSeek, Qwen, and open-weights models through a single standardized API key with automatic failover.
    • Micro-Billing at Token Scale: Managing per-token payments across dozens of model providers is a massive ledger problem that fits Stripe’s core payments infrastructure.
    • Autonomous Agent Rails: As software agents perform autonomous workflows, they require programmatic wallets and dynamic routing gateways to pay for compute per task.

    2. Developer Impact on Routing, APIs, and Pricing

    The strategic move where Stripe Acquires OpenRouter directly addresses developer lock-in and billing complexity:

    • Native Stripe Billing Integration: Developers can now bundle end-user SaaS subscriptions with pass-through per-token AI costs under a single unified dashboard.
    • No Disruption to Open Protocols: The platform will maintain its open OpenAI-compatible API endpoints and Model Context Protocol (MCP) tool integrations.
    • Enterprise SLA Guarantees: Backed by Stripe’s infrastructure, enterprise teams gain dedicated throughput and latency guarantees across global routing clusters.

    3. Key Takeaways

    • Historic Infrastructure Deal: Stripe Acquires OpenRouter for over $7 billion.
    • 8M+ Developer Reach: Consolidates routing across 400+ AI models under Stripe’s financial stack.
    • Agent Economy Foundation: Powers automated micro-payments and multi-model fallback for next-generation software agents.

    Bookmark AICodeNews.com for daily updates on AI infrastructure acquisitions, model pricing, and developer tools.

  • Alibaba Releases Qwen3.8-27B on Hugging Face: Apache 2.0 Open Weights for Local GPUs

    Alibaba Releases Qwen3.8-27B on Hugging Face: Apache 2.0 Open Weights for Local GPUs

    Alibaba Cloud’s Qwen Team has officially released Qwen 3.8 27B on Hugging Face under the fully permissive Apache 2.0 open-source license.

    Available immediately on the Hugging Face Qwen Repository, Qwen 3.8 27B delivers dense vision-language and high-performance code generation capabilities engineered specifically to run on consumer hardware without sacrificing benchmark intelligence.

    1. Core Architecture & Hardware Requirements for Qwen 3.8 27B

    Unlike massive cloud-only Mixture-of-Experts clusters, Qwen 3 8 27B strikes an optimal balance between parameter scale and local developer accessibility.

    • Single-GPU Deployment: In 4-bit GGUF or official FP8 precision (Qwen3.8-27B-FP8), Qwen 3.8 27B fits comfortably inside a single 24GB GPU (such as an Nvidia RTX 3090 or 4090) or a modern Apple Silicon Mac with 32GB of unified memory.
    • 55.6 GB BF16 Weights: The official repository provides 18 shards of uncompressed BF16 safetensors alongside official FP8 quantized checkpoints.
    • Permissive Apache 2.0 License: Organizations can deploy Qwen 3.8-27B in commercial SaaS products, private on-prem clusters, and terminal coding agents with zero licensing fees.

    2. Benchmark Performance in Software Engineering Workflows

    Early developer testing across developer communities indicates that Qwen 3.8-27B rivals larger 70B parameter models on code completion, multi-language translation, and function calling.

    • SWE-Bench & HumanEval: Scores within striking distance of proprietary closed endpoints while operating entirely offline on private workstations.
    • Ecosystem Integration: Day-one support across llama.cpp, Ollama, vLLM, SGLang, and Unsloth makes running the model locally effortless.

    3. Key Takeaways

    • Official Hugging Face Release: Qwen 3.8-27B is now live under Apache 2.0.
    • Consumer Hardware Friendly: Runs locally on single 24GB GPUs and 32GB Mac Studios using FP8 and 4-bit quantizations.
    • Zero API Dependency: 100% private, self-hosted coding intelligence with no per-token costs.

    Bookmark AICodeNews.com for daily updates on open-weight AI releases, local model deployment guides, and developer tooling.